Skip to content

Spaghetti 🍝 (tech blog)

Release on push GitHub workflow

I have for a long time been using automatic creation of releases on push for some of the projects that I've been working on. So when merging a PR with labels release:{norelease,patch,minor,major} a workflow would create the according release, e.g. v1.2.3. Recently I had to expand this functionality so that both major and minor tags (mutable) will be produced, in this case v1 and v1.2. Here is what I ended up implementing.

name: auto-release-on-push

on:
  push:
    branches:
      - main

jobs:
  release-on-push:
    runs-on: ubuntu-latest
    env:
      GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
    steps:
      - uses: rymndhng/release-on-push-action@v0.28.0
        id: release-on-push
        with:
          bump_version_scheme: patch
          tag_prefix: v
      - uses: actions/checkout@v7
        with:
          fetch-depth: 0
      - uses: haya14busa/action-update-semver@v1.5.1
        with:
          major_version_tag_only: false
          tag: ${{ steps.release-on-push.outputs.tag_name }}

There are probably other solutions doing this and maybe even better, but this is what I ended up doing.

Tofu-controller workshop

In this post I'm sharing a workshop I created for my colleagues at work recently.

Requirement

  • Local Kubernetes cluster distribution like minikube, kind, k3s, etc.
  • gh cli
  • flux cli
  • OpenTofu

Goals

  1. Install tofu-controller
  2. Create an AWS IAM role or anything you like using tofu-controller
  3. Play around
  • https://fluxcd.io/flux/installation/bootstrap/github/#bootstrap-without-a-github-pat
  • https://flux-iac.github.io/tofu-controller/
  • https://wcarlsen.github.io/#opentofu-enters-the-gitops-game

Create local cluster

Create a local Kubernetes cluster in any fashion you like. I use minikube.

minikube start --wait=all
minikube update-context

Create a public repository in your own GitHub account

Create a public repository and clone it.

gh repo create <OWNER>/<NAME> --public

Bootstrap fluxcd v2

Bootstrap fluxcd using your private key.

1
2
3
4
5
flux bootstrap git \
  --url=ssh://git@github.com/<OWNER>/<NAME> \
  --branch=main \
  --private-key-file=<PRIVATE_SSH_KEY> \
  --path=/clusters/minikube

Install tofu-controller

Add these manifests to your folder cluster/minikube/tofu-controller.yaml. Remember to commit and push it.

---
apiVersion: source.toolkit.fluxcd.io/v1
kind: HelmRepository
metadata:
  name: tofu-controller
  namespace: flux-system
spec:
  interval: 1h
  url: https://flux-iac.github.io/tofu-controller

---
apiVersion: helm.toolkit.fluxcd.io/v2
kind: HelmRelease
metadata:
  name: tofu-controller
  namespace: flux-system
spec:
  interval: 10m
  releaseName: tofu-controller
  targetNamespace: flux-system
  chart:
    spec:
      chart: tofu-controller
      version: ">=0.0.0"
      sourceRef:
        kind: HelmRepository
        name: tofu-controller
        namespace: flux-system
      interval: 1m

Verify that it works with flux get all.

Add OpenTofu code and a Terraform resource

Create a folder in the repository root called infra/ and add a file called infra/main.tf. This is where our OpenTofu code will go eventually. Remember to commit and push.

terraform {
  required_providers {
    aws = {
      source  = "hashicorp/aws"
      version = "~> 6.0"
    }
  }
}

variable "aws_region" {
  type = string
}

provider "aws" {
  region = var.aws_region
}

data "aws_iam_policy_document" "this" {
  statement {
    actions = ["sts:AssumeRole", "sts:TagSession"]

    principals {
      type        = "Service"
      identifiers = ["pods.eks.amazonaws.com"]
    }
  }
}

resource "aws_iam_role" "this" {
  name               = "tofu-ctrl-test"
  assume_role_policy = data.aws_iam_policy_document.this.json
}

Then deploy an AWS secret using your local credentials (required to already be logged in with go-aws-sso or which ever tool you use).

1
2
3
4
5
6
7
aws_creds="$(aws configure export-credentials --format env-no-export)"

printf '%s\n' "$aws_creds" |
  kubectl create secret generic aws-credentials \
    --namespace flux-system  \
    --from-env-file=/dev/stdin \
    --dry-run=client -o yaml | kubectl apply -f -

Lastly add this Terraform resource to the folder clusters/minikube/terraform.yaml. Again we need to commit and push.

apiVersion: infra.contrib.fluxcd.io/v1alpha2
kind: Terraform
metadata:
  name: test
  namespace: flux-system
spec:
  approvePlan: "auto"
  interval: 2m
  destroyResourcesOnDeletion: true
  storeReadablePlan: human
  path: ./infra
  sourceRef:
    kind: GitRepository
    name: flux-system
    namespace: flux-system
  vars:
  - name: aws_region
    value: "eu-west-1"
  runnerPodTemplate:
    spec:
      envFrom:
        - secretRef:
            name: aws-credentials

Bonus goals

Below is in no particular order.

  • Locate plans and states as Kubernetes Secrets
  • Try backup and restore of state https://flux-iac.github.io/tofu-controller/use-tf-controller/backup-and-restore-a-Terraform-state/
  • Try branch-planner https://flux-iac.github.io/tofu-controller/branch-planner/branch-planner-getting-started/
  • Write output to secrets https://flux-iac.github.io/tofu-controller/use-tf-controller/provision-resources-obtain-outputs/
  • Create multiple Terraform resources and use dependsOn
  • Perform healthChecks using outputs https://flux-iac.github.io/tofu-controller/use-tf-controller/provision-Terraform-resources-that-are-required-health-checks/
  • Is a custom backend better than Kubernetes Secrets https://flux-iac.github.io/tofu-controller/use-tf-controller/with-a-custom-backend/
  • Investigate plan-only mode
  • Create a local Kubernetes Secret remote backend and do local plans
  • Play with tfclt cli tool https://flux-iac.github.io/tofu-controller/tfctl/

Working with FluxCD HelmReleases

If you have ever worked with FluxCD and HelmReleases you know that it is very easy to change a Helm charts values or update chart version, but the problem is that it very hard to get any feedback on that change client side. Flux doesn't have functionality to render the Helm chart for you, so you can see the actual changes to the underlying manifests. Overall it is not a very fun developer experience and personally I would like it to be free of any server side stuff.

Flate to the rescue

flate is a go rewrite of the depricated tool flux-local. It offers offline rendering and diffing of HelmReleases among other things. This means that can run flate diff hr <NAME_OF_HELMRELEASE> on a change and view the diff the rendered Helm chart compare to my main branch. If I want to render the full Helm chart I would run flate build hr <NAME_OF_HELMRELEASE> and inspect the manifests. Lastly we can also use it to extract CRDs by running flate build hr <NAME_OF_HELMRELEASE> --only-crds.

flate seems to solve so many of the issues with working with FluxCD HelmReleases and I highly recommend you take it for a spin.

Cluster API bootstrap and pivot

In my investigation of learning Cluster API, I stumpled upon a thing called bootstrap and pivot using the clusterctl move command. To my knowledge it is an attempt to try and solve the chicken and the egg problem, so you can bootstrap a new target management cluster with Cluster API from a bootstrap cluster and then later pivot/move the management of the target management cluster from the bootstrap cluster to the target management cluster it self. Confusing I know, but let's try to break it down and investigate.

Bootstrap and pivot

So how would the process actually look like.

  1. Create local bootstrap cluster with e.g. minikube start
  2. Install CAPI plus providers with clusterctl init
  3. Provision new cluster (future target for management cluster) with clusterctl generate
  4. Get kubeconfig for new cluster with clusterctl get kubeconfig
  5. Backup new cluster with clusterctl move --to-folder, because the pivot later will delete resources
  6. Install CAPI plus providers on the new cluster with clusterctl init
  7. Pivot CAPI related resources to new cluster with clusterctl move --to-kubeconfig
  8. Remove local bootstrap cluster with minikube delete

The new cluster is now managing it self. This of course means that we can solve the chicken and the egg problem using only Cluster API. But it also means that all clusters created with Cluster API can now manage their own resources and create total isolation. It also removes the overhead of having a dedicated management cluster, if you cluster count is low. If this is a good idea or not I will let you think about.

Lastly here is a link to the documentation.

Replace k9s with sofka

K9s has for a long time been a tool stable tool in my toolbox. It enables easy browsing and exploraiton without too much hassle. The core functionality is decent and it is extendable through plugins, eventhough it is a little bit clunky to be honest.

Recently sofka came onto my radar, and initially I thought it was just another Rust rewrite, but to my surprise it has some killer features that I've been missing. Let's go over some of them:

  • Argo CD and Flux CD built-in capabilities for suspend, resume, and reconcile/sync their respective CustomResources with t. No requirement for the binaries.
  • Bulk actions. Use space to mark multiple resources and perform an action.
  • Deterministic, evidence-based incident view (no AI). If you press X on a broken resource it tells you why something is wrong.

I strongly recommend you take a look at this tool and see if it can replace k9s for you.

OpenTofu enters the GitOps game

It has long been established that OpenTofu/Terraform is a strong tool for managing infrastructure, and for good reason. Write your changes, review the plan, and apply once you’re happy with the outcome. The wide landscape of providers and modules makes it hard to ignore for complex setups. Then Kubernetes controllers and GitOps entered the arena, with their fancy reconciliation loops, pull-based approach, and a different lifecycle than other tools. Suddenly Terraform and OpenTofu felt ancient and slow. In this post we will see if we can make OpenTofu catch up to Crossplane, ACK, and similar projects using tofu-controller.

Introduction to tofu-controller

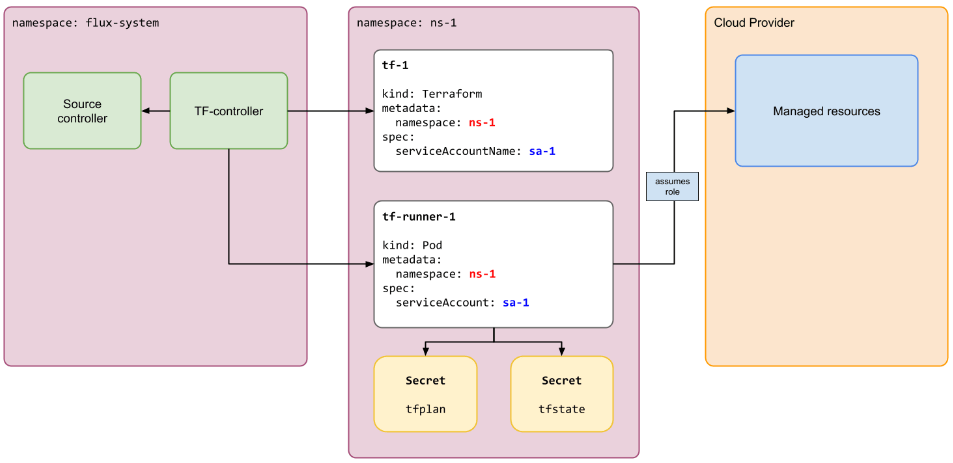
Tofu-controller should be considered an extension of FluxCD version 2, because FluxCD is a requirement. It brings OpenTofu/Terraform capabilities to FluxCD by adding a Terraform CustomResourceDefinition and a tofu-controller Deployment to your cluster. A Terraform custom resource is very similar to FluxCD’s Kustomization. At its core, we need to reference a source like a Git repository, a path to find our OpenTofu code, and a reconciliation interval. FluxCD's source controller will then pull your repository, and tofu-controller will create a pod that runs tofu apply automatically at the specified path and reconciliation interval. There is, of course, more complexity and configuration options than discussed here, but this will suffice for now. In this simple example, we have extended OpenTofu with pull-based apply and drift detection (reconciliation). By default, tofu-controller uses Kubernetes Secrets as the remote state backend, but this can be overwritten. It also stores its plan in a Secret. Below I have borrowed a high-level diagram of how it works from their documentation.

tofu-controller

Lastly, let's inspect a simple example of a minimal Terraform resource:

apiVersion: infra.contrib.fluxcd.io/v1alpha2
kind: Terraform
metadata:
  name: example
  namespace: flux-system
spec:
  interval: 5m
  approvePlan: auto
  path: ./
  sourceRef:
    kind: GitRepository
    name: example-repository
    namespace: flux-system

Conclusion

In conclusion this probably makes OpenTofu/Terraform somewhat relevant as an alternative to Crossplane, ACK and others. Tofu-controller isn't perfect in any way and should also be considered as a relative immature project. Personally I was positively surprised by the simplicity of the project and I would also consider it an viable option, because there are just so many benefits when it comes to the ecosystem around Opentofu/Terraform.

IRSA and Pod Identity compared for eventual consistency

While basically achieving the same IAM Roles for Service Accounts (IRSA) and Pod Identity namely, injecting an AWS context with temporary credentials into your Kubernetes Pod workloads. They do this in very different manner. In this post we will touch upon the differences, promises and the topic of eventually consistency.

IRSA

When provisioning an AWS EKS cluster, an OIDC provider is associated with that particular cluster. The OIDC provider is unique to the cluster and commonly lives and dies with it. We use this OIDC provider to create a federated trust with our IAM Roles to allow EKS to fetch temporary credentials. It is important to note that the trust policy also has to be aware of the Namespace and ServiceAccount used, and the ServiceAccount needs a special annotation containing the IAM Role ARN. The last bit is important for our later discussion about eventual consistency, since we provide Kubernetes with some metadata related to our IAM Role to ServiceAccount mapping. A MutatingWebhook, hidden in the control plane, picks up workloads using a ServiceAccount annotated with the intention of consuming the IAM Role credentials and injects them.

We can already realise a few things here:

  • IRSA cannot survive cluster recreation without us updating the IAM Role trust policy with the updated OIDC provider.
  • We need to provide Kubernetes with some metadata in the form of a ServiceAccount annotation.
  • EKS doesn't need to know anything about our IAM Role to ServiceAccount mapping.

Pod Identity

Pod Identity takes a different approach than IRSA to address the "cannot survive cluster recreation" problem by replacing OIDC federation with an EKS-native exchange called an association. A Pod Identity Association is a record that maps an IAM Role to one Kubernetes ServiceAccount and the record lives entirely in EKS; hence we don't need to provide any metadata to Kubernetes. The IAM Role still needs a trust policy, but it is now independent of the OIDC provider, Namespace, and ServiceAccount. For Pod Identity to work we need to enable the EKS addon that provisions a DaemonSet and a MutatingWebhook. Once a Pod Identity Association has been added, the MutatingWebhook injects credentials into the Pod.

Again, we can realise a couple of things of interest:

  • Pod Identity can survive cluster recreation, but it requires that EKS knows all the mappings between IAM Roles and ServiceAccounts.
  • We do not need to provide any metadata to Kubernetes.
  • EKS needs to know about our IAM Role to ServiceAccount mappings.

Eventual consistency discussion

Since both methods essentially use MutatingWebhooks, I would argue that having Kubernetes metadata is an important advantage for eventual consistency. Let's sketch out the scenario for Pod Identity.

  1. We create a ServiceAccount to be referenced in a Deployment and apply it to the cluster.
  2. We then later create an IAM Role and add a Pod Identity Association.

If the Deployment's resulting Pods get scheduled before I add my Pod Identity Association, the MutatingWebhook will never pick up on this and my Pods never get AWS context injected. I would need to trigger a new Deployment rollout for the MutatingWebhook to take effect.

Let's sketch the same scenario for IRSA.

  1. We create a ServiceAccount to be referenced in a Deployment. Because IRSA requires Kubernetes metadata in the form of an annotation referencing a Role ARN, we add this to the ServiceAccount up front even though the IAM Role doesn't exist yet. We apply this to the cluster.
  2. We then later create an IAM Role referencing the OIDC provider, Namespace, and ServiceAccount.

In this case our MutatingWebhook has already picked up on our intent to consume an AWS context, so even though we didn't provision the IAM Role before our ServiceAccount and Deployment, the Pods will eventually get the credentials injected without us triggering a Deployment rollout. This is because the MutatingWebhook has already mutated our Pods. Kubernetes metadata provides us with the option of declaring intent up front, allowing ordering to become irrelevant and enabling eventual consistency. It should be stated that IRSA would have the same issue as Pod Identity if we do not annotate the ServiceAccount up front.

Conclusion

It is important to stress that IRSA isn't better than Pod Identity or vice versa. They each have their strengths and weaknesses; you should consider reading this article to learn more on the topic. For this particular thought experiment, the Kubernetes metadata part becomes very handy, and I prefer relying on eventual consistency rather than relying on correct apply ordering.

Lastly, I hope that AWS will add some similar functionality to Pod Identity so that we can declare intent up front. My naive suggestion would be an optional ServiceAccount annotation that doesn't contain the IAM Role ARN, to keep the mapping lifecycle only in EKS as already implemented.

Playing with Cluster API helm addon

In the previous post, we continued the journey of playing with Cluster API and tried to cover how to get things onto a workload cluster β€” see the post here. We went through ClusterResourceSet and HelmChartProxy. In this post we will dig deeper into the capabilities of HelmChartProxy, with a focus on templating and propagating cluster infrastructure-specific details.

Why is this important?

When bootstrapping controllers and other components onto a workload cluster, we might need to provide the controllers with information that is not known upfront when provisioning the cluster. VPC ID or OIDC ARN are good examples of this. This means we may need to retrofit this information into a Helm chart afterwards.

Helm addon valuesTemplete

It turns out that the Helm addon for Cluster API has templating capabilities built in for fetching data from the spec of Cluster and ControlPlane resources. Let's see an example of this using our favorite metrics-server chart as a naive example:

apiVersion: addons.cluster.x-k8s.io/v1alpha1
kind: HelmChartProxy
metadata:
  name: metrics-server
  namespace: default
spec:
  clusterSelector:
    matchLabels:
      helm-addon: enabled
  repoURL: "https://kubernetes-sigs.github.io/metrics-server/"
  chartName: metrics-server
  options:
    waitForJobs: true
    wait: true
    timeout: 5m
    install:
      createNamespace: true
  valuesTemplate: |
    commonLabels:
      test: im-a-static-label # static label
      vpcId: {{ .ControlPlane.spec.network.vpc.id }} # label read from control plane resource
      host: "{{ .Cluster.spec.controlPlaneEndpoint.port }}" # label read from cluster resource

We can verify that the metrics-server Deployment in the target cluster will have labels containing the VPC ID and control plane endpoint port, read from the management cluster's knowledge of the workload cluster.

This is a significant advantage the Helm add-on has over ClusterResourceSet and can be very valuable.

Playing with Cluster API continued

In the previous post, we bootstrapped a Cluster API management cluster onto a local Kubernetes distribution and used it to provision a workload cluster. We also made sure that we could take backups of resources related to the workload cluster and restore them, reducing the need for long-lived management clusters. See the post here. In this post we will focus more on Cluster API-specific ways to deploy resources onto the workload cluster, which is important for bootstrapping GitOps capabilities, among other things. Note that all methods covered here apply resources to the workload cluster once it is ready.

ClusterResourceSet

With Cluster API we can enable ClusterResourceSet by setting the experimental feature flag EXP_CLUSTER_RESOURCE_SET=true when bootstrapping the management cluster. This ensures that the custom resource ClusterResourceSet becomes available on our management cluster. But how does it work?

The concept is pretty simple to grasp if we inspect an example of the resource:

---
apiVersion: addons.cluster.x-k8s.io/v1beta2
kind: ClusterResourceSet
metadata:
  name: my-customresourceset
  namespace: default
spec:
  clusterSelector:
    matchLabels:
      clusterresourceset: enabled
  resources:
    - kind: ConfigMap
      name: my-manifests
  strategy: ApplyOnce

---
apiVersion: v1
kind: ConfigMap
metadata:
  name: my-manifests
  namespace: default
data:
  namespace.yaml: |-
    ---
    apiVersion: v1
    kind: Namespace
    metadata:
      name: my-new-namespace

A ClusterResourceSet targets a cluster using label selectors, so we may label our workload cluster to make this work. Then it references resources like ConfigMap and Secret (I haven't tried this with Secret) that contain the manifests we want applied to our target cluster. In this example it is just a namespace, but it can be arbitrarily complex. Lastly, the strategy can be ApplyOnce or Reconcile. Note that if we delete any resources in our ConfigMap, Cluster API will not delete the corresponding resources in the target cluster, to my knowledge. We could wish for better controller functionality, but for bootstrapping it probably works fine. You can probably read between the lines that I'm not the biggest fan.

Helm addon

The second method we will cover is the Helm addon, which can be enabled by adding --addon helm when bootstrapping the management cluster. This will make the HelmChartProxy custom resource available and install a controller called caaph. If we inspect an example resource where we deploy the metrics-server Helm chart, we will see that it follows the same concept: it uses a cluster label selector, and the rest of the spec relates to the Helm chart we wish to consume.

apiVersion: addons.cluster.x-k8s.io/v1alpha1
kind: HelmChartProxy
metadata:
  name: metrics-server
  namespace: default
spec:
  clusterSelector:
    matchLabels:
      helm-addon: enabled
  repoURL: "https://kubernetes-sigs.github.io/metrics-server/"
  chartName: metrics-server
  options:
    waitForJobs: true
    wait: true
    timeout: 5m
    install:
      createNamespace: true

Unlike with ClusterResourceSet, when we delete a HelmChartProxy resource the chart will also be removed from the target cluster. So it behaves as we'd expect from a proper controller. If your bootstrapping needs are covered by Helm, I would strongly suggest this as the preferred method.

Playing with Cluster API

I have for a long time wanted to play around with Cluster API (CAPI) and I finally got around to test it at work recently. This post will mainly cover how to quickly get up and running using a local Kubernetes distribution as management cluster and provisioning an AWS EKS cluster with CAPI.

Bootstrapping

CAPI requires a CloudFormation stack to be provisioned and by using clusterawsadm we can first output a bootstrap config file for us to tweak and then create the stack.

1
2
3
4
5
# Output bootstrap config
clusterawsadm bootstrap iam print-config > bootstrap-config.yaml

# Create CloudFormation stack
clusterawsadm bootstrap iam create-cloudformation-stack --config bootstrap-config.yaml

Up front the bootstrap-config.yaml file doesn't need any tweaking, but it's good to have if we need to do changes at a later stage.

# Update CloudFormation stack
clusterawsadm bootstrap iam update-cloudformation-stack --config bootstrap-config.yaml

Local management cluster

For some reason I like minikube, but you can choose any other local Kubernetes distribution like k3s, kind etc.. Let's start the cluster.

# Start local Kubernetes cluster and wait for it to be ready
minikube start --wait=all

We now need to initialize CAPI with an AWS provider on our local management cluster using clusterctl.

1
2
3
4
5
6
7
# Initialize CAPI with AWS specific provider
AWS_B64ENCODED_CREDENTIALS=$(clusterawsadm bootstrap credentials encode-as-profile --profile ${AWS_PROFILE}) \
  EXP_MACHINE_POOL=true \
  EXP_CLUSTER_RESOURCE_SET=true \
  CAPA_EKS_IAM=true \
  CAPA_EKS_ADD_ROLES=true \
  clusterctl init --infrastructure aws

We set a bunch of feature flags that are good defaults and I find enablement of EXP_MACHINE_POOL absolutely essential for simplification.

  • EXP_MACHINE_POOL enables the experimental Machine Pool feature, allowing you to manage groups of machines as a single unit with common configurations.
  • EXP_CLUSTER_RESOURCE_SET enables experimental ClusterResourceSet support, which lets you automatically apply resources to clusters when they're created.
  • CAPA_EKS_IAM enables IAM role management for EKS clusters, allowing Cluster API to create and configure IAM roles needed by EKS.
  • CAPA_EKS_ADD_ROLES enables automatic addition of required IAM roles to worker nodes, ensuring they have proper permissions to join and operate in the EKS cluster

The above command will install cert-manager and the following Cluster API providers: cluster-api, bootstrap-kubeadm, control-plane-kubeadm and infrastructure-aws.

Provision workload cluster

Before we begin provisioning, an SSH key pair is required, so we'll provision one using the AWS CLI.

# Create SSH key pair
aws ec2 create-key-pair --key-name workload --output json

We are now ready to generate the manifests for our new cluster.

# Create directory for cluster manifests
mkdir k8s/

# Generate cluster manifests
AWS_REGION=${AWS_REGION} \
  AWS_SSH_KEY_NAME=workload \
  AWS_CONTROL_PLANE_MACHINE_TYPE=t3.large \
  AWS_NODE_MACHINE_TYPE=t3.large \
  WORKER_MACHINE_COUNT=1 \
  CLUSTER_NAME=workload \
  CLUSTER_VERSION=1.36.1 \
  clusterctl generate cluster ${CLUSTER_NAME} --kubernetes-version ${CLUSTER_VERSION} --flavor eks-managedmachinepool > k8s/manifests.yaml

It is advised that you inspect the manifests before applying them.

# Apply workload cluster manifests
kubectl apply -f k8s/

We can now watch progress on workload cluster provisioning.

# Watch workload cluster provisioning
clusterctl describe cluster workload

It will take some time to provision, so go grab something to drink. Once provisioned we can gain access to our new workload cluster using the following command.

# Get kubeconfig of workload cluster
clusterctl get kubeconfig workload

Backup and restore

We can easily backup and restore using the following commands.

1
2
3
4
5
6
7
8
# Create backup folder
mkdir backup/

# Take backup
clusterctl move --to-directory backup/

# Restore from backup
clusterctl move --from-directory backup/

This means that our management cluster can potentially become ephemeral, assuming we can live without reconciliation.

Clean up

We can easily clean up. But it is important that we wait for the CAPI controllers to clean up AWS resources and that takes time.

# Take backup (just to be sure)
clusterctl move --to-directory backup/

# Delete workload cluster (IMPORTANT: this will take some time since the controllers need to do cleanup, so be patient)
kubectl delete -f k8s/

# Delete SSH key pair
aws ec2 delete-key-pair --key-name default

# Delete management cluster
minikube delete

# Delete CloudFormation stack
clusterawsadm bootstrap iam delete-cloudformation-stack